Ph.D. candidate · UC Berkeley
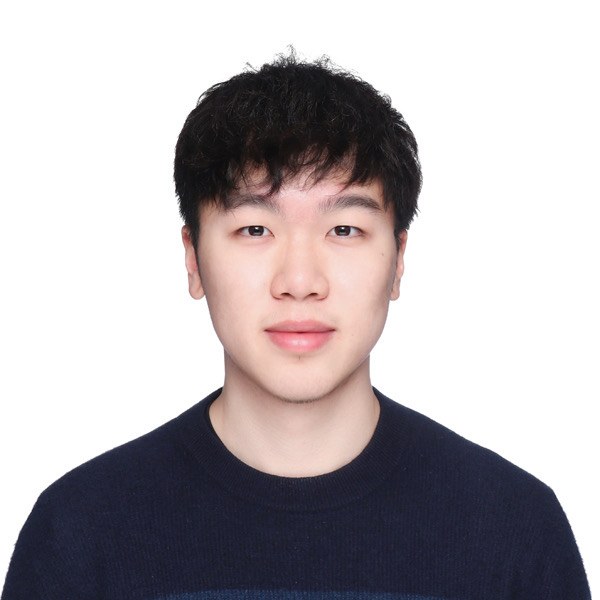
Junyu (James) Guo
I design decision-making algorithms for agents that operate under uncertainty, from reinforcement learning to the reasoning of large language models.
 Berkeley, CA
01 / About
About me
I am Junyu Guo (James), a Ph.D. candidate at the University of California, Berkeley, where I am fortunate to be advised by Prof. Javad Lavaei. My research focuses on designing efficient decision-making algorithms for agents operating under uncertainty, with particular emphasis on data-driven sequential decision-making for Large Language Models (LLMs). I am also fortunate to work with Prof. Costas Spanos (Berkeley EECS), Prof. Ming Jin and Dr. Shangding Gu, as well as Liyuan Liang and Yuchen Fang from Prof. Lavaei’s group.
Prior to Berkeley, I completed my undergraduate studies in the Department of Mathematical Sciences at Tsinghua University in Beijing, China, where I was advised by Prof. Chenxu Li and Prof. Yiwen Shen on efficient simulation for portfolio allocation in incomplete markets.
During my time at Tsinghua, I was also an exchange student at Cornell University, collaborating with Prof. Andreea Minca and Prof. Qiaomin Xie on reinforcement learning for mean field games.
Beyond research, I am an avid football fan (Manchester City and FC Barcelona), and I enjoy traveling, music, hiking, and playing soccer.
02 / Focus
Research interests
Reinforcement Learning
Efficient algorithms for sequential decision-making under uncertainty, with emphasis on meta-RL for quick adaptation to non-stationary environments.
LLM Reasoning
Improving the decision-making and reasoning of large language models through uncertainty estimation and quantification.
Trustworthy AI
AI systems that are interpretable, explainable, fair and privacy-preserving.
03 / Research
Selected papers
-
2026
When Context Changes: Understanding Update Failures in LLMs
LLM agents can answer with an old value of a variable even when the updated one is still in context, a failure we call stale binding. We introduce the Controlled In-Context Memory (CICM) benchmark, trace the failure to attention drifting toward old values, and correct most of these errors by redirecting attention without further training.
-
2026
LLMs Should Express Uncertainty Explicitly
Trains language models to state their uncertainty in two ways: a verbalized confidence score after reasoning, and explicit uncertainty markers during reasoning. This reduces overconfident errors and gives downstream systems such as retrieval-augmented generation a signal to act on.
-
2025
Don't Trade Off Safety: Diffusion Regularization for Constrained Offline RL
DRCORL uses a diffusion model to regularize policy learning in offline safe reinforcement learning, and gradient manipulation to resolve conflicts between reward and safety objectives, while keeping inference fast.
-
2025
Meta Thinker: Thinking What AI Thinks
Asks whether LLMs can pick the right reasoning style for a problem on their own. After comparing five reasoning paradigms on mathematical, logical and commonsense benchmarks, we propose a meta-thinking prompt algorithm that selects or synthesizes a style from the input, improving both accuracy and token efficiency.
-
2025
04 / News
What's new
- Sep 2026
New preprint: When Context Changes: Understanding Update Failures in LLMs.
- Jul 2026
Passed my Ph.D. qualifying exam and became a Ph.D. candidate.
- May 2026
Joined TikTok (Data and Privacy Office, San Jose) as a Machine Learning Engineer Intern.
- Apr 2026
New preprint: LLMs Should Express Uncertainty Explicitly.
- Dec 2025
Don’t Trade Off Safety: Diffusion Regularization for Constrained Offline RL appears at NeurIPS 2025, and Meta Thinker: Thinking What AI Thinks at the NeurIPS MATH-AI workshop.
- Sep 2025
New preprint: StyleBench: Evaluating Thinking Styles in Large Language Models, with code.
- Aug 2025
Graduate Student Instructor for INDENG 160: Nonlinear and Discrete Optimization in Fall 2025 and Spring 2026.
- Sep 2024
Joined Prof. Javad Lavaei’s group at UC Berkeley.
- Aug 2024
Started my Ph.D. at UC Berkeley, supported by the Wolff Fellowship.
05 / Writing
Notes & blog
Meta RL
Different from Non-stationary RL setting, in meta learning we try to solve a series of tasks using the learned knowledge, which is...
Read noteNon-stationary RL
Non-Stationary RL Usually we consider optimizing an objective under a stationary MDP with a fixed transition and reward function. We can learn...
Read noteJoin A New Group
Today I’m glad to announce that I’m officially a member of Prof. Javad Lavaei’s group, and I’m really looking forward to work...
Read post06 / Contact
Let's talk research.
I'm always glad to hear from people working on reinforcement learning, LLM reasoning or trustworthy AI. Email is the best way to reach me.